cq4oe-benchmark
CQ4OE: A benchmark for assessing the LLM-assisted ontology generation from competency questions

This repository contains a benchmark for assessing the performance of different LLM-based ontology generation methods from competency questions. The benchmark is built on six domain experts annotated ontologies that are exact mirroring the corresponding competency questions.
The gold standards for both tasks and entire annotation process are also published as a dataset on HuggingFace: oeg/CQ4OE;
Task 1: CQ2Term Given a competency question, the LLM-based method aims to extract the classes and properties required to answer it.
Task 2: CQ2Onto Given a set of competency questions in any domain, processing by LLM-based ontology generation method, producing a full OWL ontology.
Source Ontologies:
- Wine: Wine Ontology
- VGO: VideoGame Ontolgy
- SWO: Software Ontology
- AWO: African wildlife Ontology
- ODRL: Open Digital Rights Language Ontology
- Water: SAREF4WATR Ontolgy
Leaderboard
Using CQ4OE
If you want to use CQ4OE with your generated ontologies from your own baselines, please see the usage instructions.
Contributing to CQ4OE
If you wish to submit your own results, please open an issue with:
- The generated ontologies (a .ttl file for each)
- The task it addresses (CQ2Term or CQ2onto)
- Details on the model / approach used in the generation.
We’ll do our best to verify your results. Once the results have been verified, they will be added to the repository.
Annotation
The annotated ontologies in this benchmark are not just snapshots of existing ontologies. Every class, property and axiom is explicitly tied back to the competency questions. This section documents how that link was built so anyone adding a new domain can do the same thing.
Annotation Pipeline
The annotation runs as a four-phase pipeline. Phase 1 fixes the conceptual backbone of the source ontology; Phase 2 filters and annotates the CQs; Phase 3 augments the CQ set so that each core term is covered; Phase 4 composes the two gold standards (CQ2Term and CQ2Onto) with full CQ-to-term and CQ-to-axiom provenance. Each decision is reviewed by three people independently (one annotator with OE background and two reviewers), and an item is kept only if at least 2 of 3 agree.
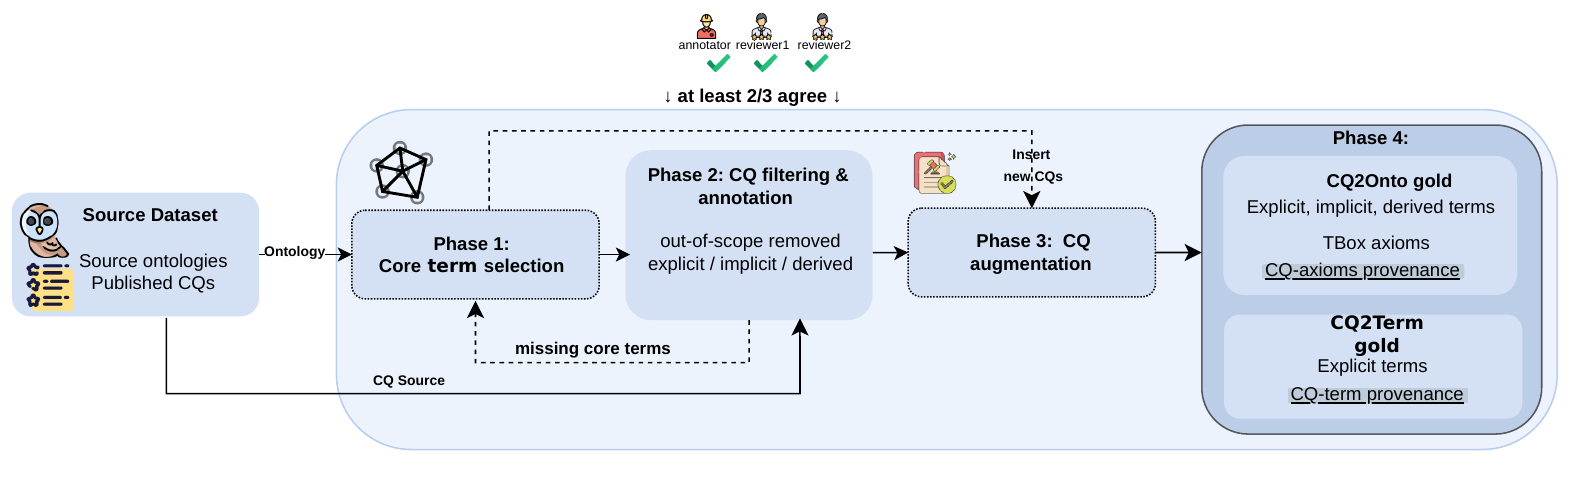
Figure 1. CQ4OE annotation pipeline. Include 4 Phases.
Annotation Guideline
For each source ontology, the annotation runs in three stages.
For each source ontology, the annotation runs through the four phases shown in Figure 1.
Phase 1 — Core term selection. Before processing any competency question, domain experts identify the conceptual backbone (key concepts and properties) of the source ontology using two complementary criteria. Quantitatively, named classes and properties are ranked by in- and out-degree, and the highly connected nodes are taken as initial candidates. Qualitatively, the ontology is visualized with owl2diagram and inspected against the published requirements. A term is retained as a core term if it is highly connected, visually central, and domain-relevant. This keeps the backbone of the source ontology with maximum coverage.
Phase 2 — CQ filtering and annotation. Filter out CQs that use external knowledge or out-of-scope concepts, that cannot be answered from the ontology, or that target instance-level (ABox) rather than TBox knowledge. For each retained CQ, annotate its terms in three categories:
- Explicit: terms that appear lexically in the CQ. Example: in “Which animal eats which other animal?”,
Animalandeatsare explicit. - Implicit: terms expressed through synonymous phrasing. Example: in a wine CQ saying “used to make”,
madeFromGrapeis implicit. - Derived: terms required to answer the CQ but not stated in it (including answer-side concepts). Example: a CQ about “duration” requires
hasStartTimestampandhasEndTimestampto formulate the answer.
Phase 3 — CQ augmentation. Check whether each core term selected in Phase 1 is required by at least one annotated CQ. For each uncovered core term, domain experts author a brand-new CQ that (i) is answerable from the source ontology, (ii) requires the uncovered term, and (iii) follows the style of the original CQs. New CQs are annotated as in Phase 2 and marked with ⋆ in the dataset.
Phase 4 — Gold standard construction. Build two gold standards in parallel:
-
CQ2Term gold. For each CQ with at least one Explicit term, keep its Explicit classes and properties. Output: CQ-to-term provenance. CQs without Explicit terms are excluded here, but stay in CQ2Onto.
-
CQ2Onto gold. For each CQ, take its Explicit + Implicit + Derived terms, extract a fair and equivalent ontology fragment containing them and the axioms involving them, and drop ABox assertions. Keep an axiom if removing it would make the CQ unanswerable. Output: a CQ-aligned sub-ontology with CQ-to-axiom provenance.
Missing Elements are documented but are not part of either gold standard.
All decisions in Phases 1–4 follow the review protocol introduced above (three people independently, ≥ 2/3 agreement to keep, otherwise discard).
CQ: Which animals are the predators of [these animals]?
- Explicit Class: Animal
- Explicit Property: —
- Implicit Class: —
- Implicit Property: eats (CQ says “predators of”, ontology has
eats) - Derived Class: Carnivore (needed to answer; CQ doesn’t mention it)
- Derived Property: —
- Missing Element: “predators” is not in the ontology; expressed via
eats+Carnivore
Dataset Description
We have selected six ontologies in three diferent scales: | Ontology | Tier | Source CQs | Retained | New ⋆ | CQ2Onto set | CQ2Term set | |———-|——|———–:|———:|——:|————:|————:| | Wine | small | 7 | 4 | 1 | 5 | 5 | | AWO | small | 14 | 7 | 0 | 7 | 7 | | ODRL | medium | 35 | 13 | 6 | 19 | 19 | | Water | medium | 43 | 21 | 0 | 21 | 20 | | VGO | large | 68 | 30 | 1 | 31 | 22 | | SWO | large | 88 | 35 | 0 | 35 | 26 |
LLM Usage:
This repository evaluates LLM-based methods for two tasks: CQ2Onto (full-ontology generation) and CQ2Term (term-level generation), with the selection of baseline LLMs.
Baseline LLMs Selection
- Qwen-3.6 Series:
- Qwen-3.6-27B: Open-source dense 27B parameter model
- Qwen-3.6-35B: Open-source Mixture-of-Experts model, 35B total parameters with only 3B active per token
- Qwen-3.6-flash: Closed-weights API-only low-latency model
- Qwen-3.6-plus: Closed-weight API-only flagship model with 1M context window
- Gemma-4 Series:
- Gemma-4-26B: Open-source Mixture-of-Experts model with 4B active per token
- Gemma-4-31B: Open-source dense 31B parameter model
- Deepseek Series:
- Deepseek-V3.2-671B: The previous-generation flagship, Mixture-of-Experts model from Deepseek.
- Deepseek-V4-flash-284B: Efficient Mixture-of-Experts model with 13B activate parameter
- Deepseek-V4-1.6T: Flagship Mixture-of-Experts model with 49B activate parameter, 1M context window.
CQ2Onto
This repository evaluates three different LLM-assiat ontology generation methods.:
- normal: Give the model all the CQs and ask for the OWL ontology in one shot.
- Cq-by-Cq Generation: generate a partial ontology per CQ and merge them. Slower but the model has to think about each question individually.
- MASEO: Multi-Agent System for Explainable Ontology Generation.
CQ2Term
One LLM-based method for term-level prediction:
- zero-shot term prediction: Given a competency question, the model directly outputs the classes and properties required to answer it.
Prompts
The prompts that drive every model for each method is under CQ2Onto/prompts/ and CQ2Term/prompts/. They are kept in plain JSON, one file per generation method. Every prompt file is a JSON array of agent objects. Each object has three fields:
[
  {
    "agent": "the name of the LLM-based agent",
    "instruction": "the system message of the given agent",
    "prompt": "the user message designed for the task corresponding to the agent"
  }
]
Evaluation
The benchmark is organized as tasks → dimensions → metrics. A task is an evaluation track (CQ2Onto, CQ2Term); a dimension is one aspect evaluated within a task; a metric is a single measurement applied to a dimension. Definitions, formulas, and persistent identifiers for every dimension and metric are in the catalogue.
To submit a new model: place its outputs under the corresponding predictions/ folder and run the script. The pipeline locates the gold standard, runs every dimension, and writes per-dataset and per-model results to 03_evaluation_results/ and 04_summary/.
# CQ2Term
cd CQ2Term && python scripts/run_all_cq2term.py

# CQ2Onto, all three generation strategies
cd CQ2Onto && python scripts/run_all_evaluation_agent_4datsets.py
CQ2Onto
Given a set of competency questions, the LLM produces a full OWL ontology. The output is evaluated against a CQ-aligned gold OWL ontology along the dimensions below. The first dimension yields a one-to-one term alignment that the others reuse to translate predicted vocabulary into gold vocabulary.
ClassProperty- Target: Do the generated classes and properties match the gold ones?
- Metrics:
HardMatch,SequenceMatch,LevenshteinDistance,JaroWinklerDistance,SemanticCosineSimilarity,AggregatedTop3;Precision,Recall,F1.
PropertyCharacteristicsTriple- Target: Do the generated domain/range triples match the gold ones?
- Metrics:
Precision,Recall,F1;EmbeddingDiagnostic.
Axiom- Target: Do the generated TBox axioms match the gold ones at the atomic level?
- Metrics:
Precision,Recall,F1;EmbeddingDiagnostic;AtLeastOneCoverage,MeanCoverage,FullCoverage.
HierarchyClosure- Target: Does the generated ontology entail the same class and property subsumptions as the gold one? Closure is computed with the HermiT reasoner.
- Metrics:
Precision,Recall,F1;ClosureRescueCoverage.
CQCoverage- Target: For each CQ, how many of its required TBox axioms appear in the generated ontology?
- Metrics:
AtLeastOneCoverage,MeanCoverage,FullCoverage;ClosureRescueCoveragecredits hierarchy axioms reachable through reasoner closure.
CQ2Term
Given a single competency question, the LLM outputs the classes and properties needed to answer it. The output is evaluated against the explicit term set annotated for that CQ.
ClassProperty- Target: Do the generated classes and properties match the gold ones for the CQ?
- Metrics:
HardMatch,SequenceMatch,LevenshteinDistance,JaroWinklerDistance,SemanticCosineSimilarity,AggregatedTop3; globalPrecision,Recall,F1.
CQCoverage- Target: Are the required terms generated under the CQ that requires them?
- Metrics:
AtLeastOneCoverage,MeanCoverage,FullCoverage.
Acknowledgement
This work was supported by the grant SOEL: Supporting Ontology Engineering with Large Language Models PID2023-152703NA-I00 funded by MCIN/AEI/10.13039/501100011033 and by ERDF/UE. The authors would also like to thank the EDINT (Espacios de Datos para las Infraestructuras Urbanas Inteligentes) ontology development team for sharing the project resources for evaluation purposes.